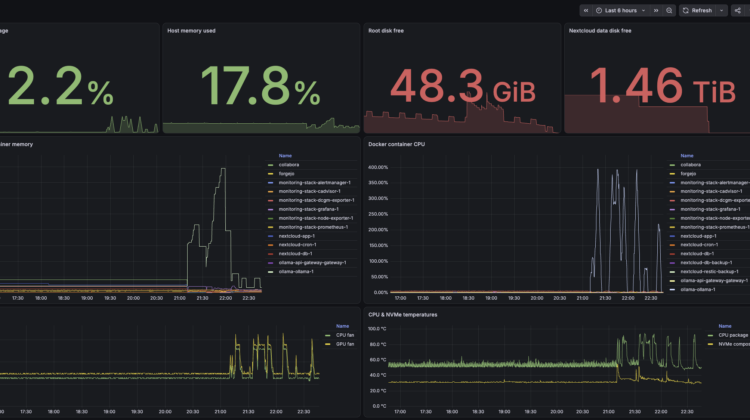
Nextcloud for storage, Forgejo for Git, Collabora, Prometheus + Grafana for monitoring – and increasingly, local AI workloads through Ollama.
The fun part in this graph is around 21:00.
That’s Qwen 14B starting to do some actual work.
Memory goes from almost nothing to ~6 GB, CPU briefly pushes across multiple cores, CPU temperature shoots up, and the fans immediately respond.
It’s interesting seeing the physical cost of inference plotted so clearly rather than treating an LLM as some abstract API call.
I’m experimenting with using these local models as worker agents behind InnomightLabs – keeping large datasets/files local and letting a larger remote agent orchestrate them without shipping all the underlying data back and forth.
Still early, but having your own little AI compute layer at home is surprisingly useful.
Leave a Reply